Config Reference: Overview
Every Ubunye task is driven by a single config.yaml file. This page is for anyone
writing one: it explains the top-level keys, which command catches which mistake,
and links to a page for each section.
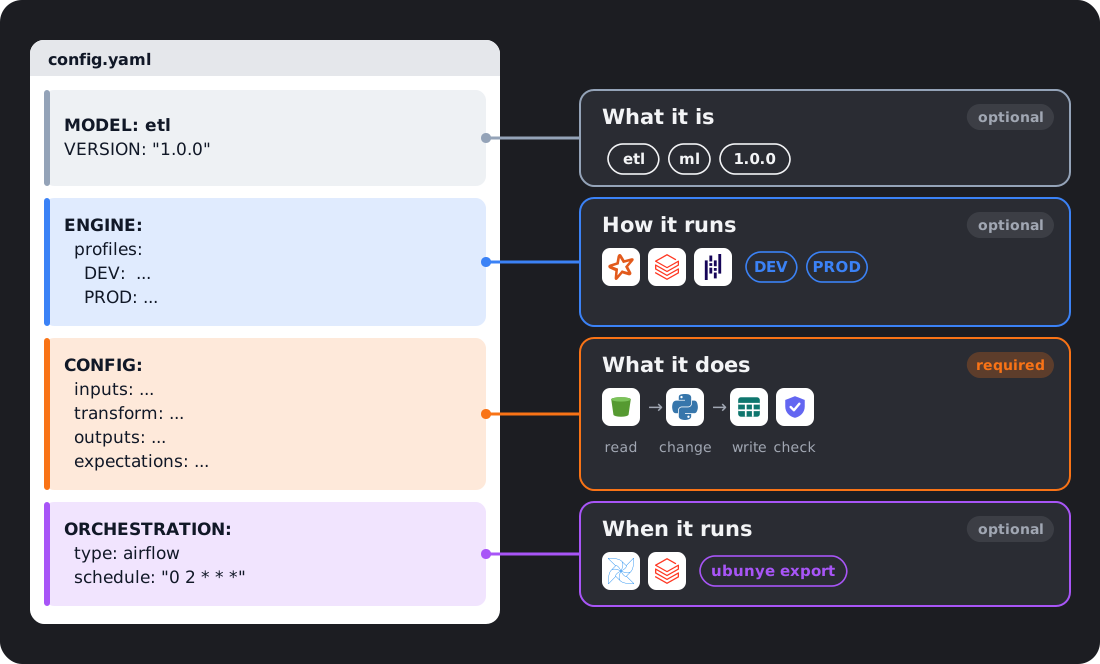
Top-level keys
MODEL: etl          # optional: job type, etl | ml (defaults to etl)
VERSION: "1.0.0"    # optional: semver string (defaults to "0.0.0-dev")

ENGINE: ...         # optional: Spark settings and per-profile overrides
CONFIG: ...         # required: inputs, transform, outputs, expectations
ORCHESTRATION: ...  # optional: metadata for `ubunye export`
| Key | Type | Required | Default | Description |
|---|---|---|---|---|
MODEL |
etl | ml |
No | etl |
Declares the job type |
VERSION |
semver string | No | "0.0.0-dev" |
Pipeline version (MAJOR.MINOR.PATCH, optional -prerelease suffix) |
ENGINE |
EngineConfig | No | none | Spark conf, catalog and schema, per-profile overrides |
CONFIG |
TaskConfig | Yes | none | Inputs, transform, outputs, expectations |
ORCHESTRATION |
OrchestrationConfig | No | none | Export metadata for orchestrators |
CONFIG holds five keys: inputs and outputs (both required, at least one
entry each), transform (optional), expectations (optional) and requires
(optional: upstream tasks that must have succeeded for this batch first, see
Job health and upstream checks).
Set MODEL and VERSION explicitly in production pipelines where job type or
version is load-bearing (lineage records, model registry, orchestrator
metadata). For quick local iteration the defaults are fine.
Jinja templating
Config values are filled in by Jinja2 ({{ ... }} placeholders) before the
config is checked. You can use environment variables, CLI-injected variables, and
filters in any value in the YAML:
CONFIG:
  inputs:
    events:
      format: hive
      db_name: "{{ env.HIVE_DB | default('raw') }}"
      tbl_name: events_{{ dt | default('2024-01-01') | replace('-', '_') }}
See Jinja Templating for all supported syntax.
Validation
Ubunye checks the rendered YAML against a strict schema, written with Pydantic (a Python library that checks data against declared fields and types). Unknown fields are rejected with typo suggestions; undefined Jinja variables fail immediately. Run validation before deploying:
Which command catches what
Three commands check a task before it runs. Each catches different mistakes, so run
validate in CI, and plan and doctor on the machine that will run the task.
| Mistake | validate |
plan |
doctor |
|---|---|---|---|
| Unknown or misspelt key, wrong type (schema) | yes | yes | yes |
A connector key that connector does not read (paht: on s3) |
yes | yes | yes |
| A template variable that is not set | yes | yes | yes, and names each missing environment variable |
A secret:// provider name that does not exist |
yes | yes | yes |
| A secret provider whose package is not installed | no | no | yes |
A write mode the connector cannot do (jdbc with mode: merge) |
no | yes | no |
overwrite_partitions with no partitionBy or replace_where |
no | yes | no |
| A local input path with nothing there | no | yes | no |
A connector the backend cannot serve (jdbc on pandas) |
with --backend |
with --backend |
no |
A profile name that is not under ENGINE.profiles (default DEV) |
yes | no | no |
| Missing packages: Java, Delta, a backend, a plugin | no | no | yes |
validate and run check the profile name the same way, and both default to
-m DEV. See
Engine & Profiles.
Strict field checking
Every config section rejects unknown keys. A typo like ENGNE triggers a
ConfigFieldError with a "Did you mean?" suggestion.
Input and output blocks are checked by their connector. Each built-in connector
declares the keys it reads, so a typo such as paht: on an s3 input is
refused with the closest real key. A third-party connector that declares no
keys accepts any key. See Writing a Plugin.
Strict template variables
A {{ var }} that is not given as a CLI variable or environment variable stops the
config from loading, instead of silently becoming an empty string. (Jinja calls this
mode StrictUndefined.) Use | default(...) for optional values.
Reference pages
| Section | Description |
|---|---|
| Inputs & Outputs | CONFIG.inputs and CONFIG.outputs: connector format and options |
| Expectations | CONFIG.expectations: checks on inputs and outputs |
| Upstream checks | CONFIG.requires: do not start until an upstream task succeeded for this batch |
| Engine & Profiles | ENGINE: Spark conf, catalog, schema and profiles |
| Transform | CONFIG.transform: the task class and its params |
| Orchestration | ORCHESTRATION: schedule, retries, tags, platform-specific settings |
| Jinja Templating | Variable interpolation, filters, and best practices |
| Secrets | secret:// references to a secret store |