ADR 006: The run record is correct before it is sold
Status: accepted, 0.7.0
Context
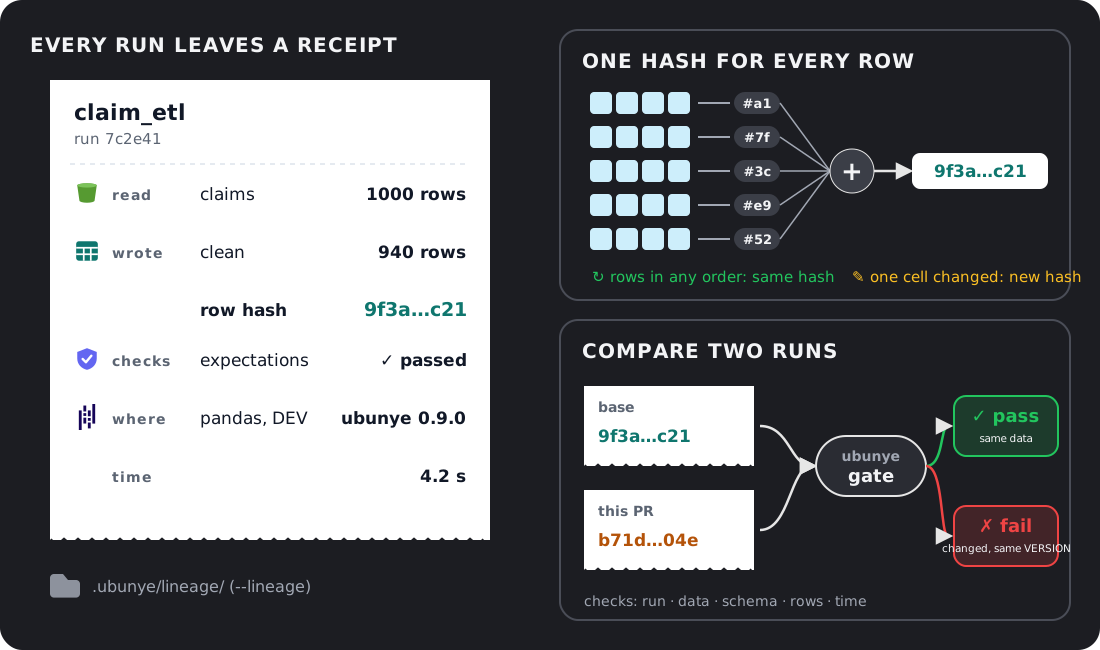
--lineage leaves a record of every run: what was read, what was written, and
a data hash per output, so ubunye lineage compare can say whether two runs
produced the same data. Before 0.7.0 that hash could not carry the claim:
- it read a 1 percent sample, so most changes were invisible to it;
- on Spark it depended on row order, so a repartition changed it;
- on pandas it failed quietly and recorded the schema hash as the data hash, so any two frames with the same columns "matched";
- runs from
run_taskand the notebook were stored under a different name and folder from CLI runs, and the notebook recorded nothing at all.
Decision
One hash, rows-v1, over every row. Each row becomes one canonical line:
a JSON object with columns sorted by name, written exactly as Spark's to_json
writes it (timestamps as UTC text to the microsecond, doubles the Java way, so
Double.MIN_VALUE is 4.9E-324 and the smallest float 1.4E-45, a control
character without a short escape as \u000B with upper case hex, NaN
as "NaN", nulls left out). The line's SHA-256 is cut into two 64-bit numbers
and each is added up over all rows. Adding does not care about order.
| Promise | How |
|---|---|
| Every row counts | All rows are hashed, in the same pass as the row count |
| Row order does not | The per-row hashes are added, and addition is order free |
| Column order does not | Columns are sorted by name first |
| Any change is seen | One different cell changes one line, so the sums |
| Null is not NaN | null is left out; NaN is written "NaN" |
| Timezone does not matter | Timestamps are written in UTC |
| Same on every engine | Spark runs it as one aggregation; pandas builds the identical line |
Types by one set of names. The hash covers the schema too, with every type written by the same name on every engine:
| Spark | Arrow / pandas | Name in the hash |
|---|---|---|
tinyint, smallint, int, bigint |
int8 to int64 |
int8, int16, int32, int64 |
float, double |
float32, float64 |
float32, float64 |
boolean |
bool |
bool |
string, varchar, char |
string, large_string |
string |
binary |
binary |
binary |
date |
date32 |
date |
timestamp / timestamp_ntz |
timestamp with / without a zone |
timestamp / timestamp_ntz |
decimal(p,s) |
decimal128(p,s) |
decimal(p,s) |
array, map, struct |
list, map, struct |
list<...>, map<...,...>, struct<name:type,...> |
Maps are unordered (clarified in 0.8, F-015 review). A map has no entry
order, but Spark keeps whatever order a map was built in, and that order differs
between engines, between Spark's JVM versions and between Spark classic and
Spark Connect. So before the line is written, every map's entries are sorted by
key, recursively (maps inside structs, arrays and maps too). On Spark this is
done in the expression (map_keys, array_sort, transform, element_at,
map_from_arrays), and only for columns whose type holds a map, so other
columns cost nothing. A map's null values are written as null, as Spark's
to_json writes them; only a struct's null fields are left out. Before this, the
pandas side dropped null map values and kept the insertion order, so a map
column could hash differently on the two engines. Digests of tables with map
columns change; digests of tables without maps do not. The change landed before
0.8.0 was released, so no published digest moved.
A backend whose frames are neither Spark nor pandas is hashed from its port
(collect() and schema), so its schema must give these names. The backend
conformance suite (ubunye.testing.backend_conformance) checks it by requiring
the same hash as the reference.
On Spark the work stays on the cluster: one agg returns three numbers. The
integration tier checks that Spark and pandas give the same hash for the same
table (nested types, NaN, awkward text, a non-UTC session), and that a whole
task run on both engines leaves identical receipts.
Honest failure. If the rows cannot be read, the record has no data hash
and says why (hash_error). It never substitutes the schema hash.
A complete record. Each record also carries the Ubunye version, the
backend, the template variables (dt, dtf, mode), and each output's
hash_method.
One place. The CLI, run_task, run_pipeline and the notebook all store
records under <usecase_dir>/.ubunye/lineage/<usecase>/<package>/<task>/, with
the same identity, so ubunye lineage list finds every run.
Consequences
- Hashing every row costs one pass over each output. On Spark it runs where the
data is; only three numbers come back. Until ADR 009 that pass also computed the
output a second time (the transform, its joins, its source reads), and could hash
rows that were never written (F-039, F-040). Since ADR 009 a recorded Spark output
is computed once and held, and the hash reads the held rows; each output step's
hash_basissays which it was. Measured (E-06 job, 5,000,000 rows, dev box, Spark 4.2 local, median of 3):--lineage1.83 times the plain job (was 2.32), 17 Spark jobs (was 18), the 5 million row source read 3 times (was 5). The rest of the cost is the hash itself, which grows with the rows (F-041). - On pandas the hash runs on this machine's cores (F-038). A table of 500,000 rows
or more is cut into runs, and each run is hashed by a helper process, a fresh
Python that loads only the hash code. Each helper sends back two sums, and the
sums add up to the same digest one process gives: every row is still hashed.
If any helper fails, the calling process hashes the whole table itself.
UBUNYE_HASH_WORKERScaps the helpers. It defaults to the number of cores, at most 4, and is never more than the usable cores; hashes running at once in one process share the cap.1(or0, or anything that is not a number) hashes in the calling process only, as it did before. A helper checks it runs the caller's hash code (by its SHA-256) and the caller's pyarrow, or gives no answer; a helper past its deadline is stopped. Memory, containers and frozen apps: see Deploying anywhere. - A table in many small Arrow chunks (a folder of many small files) is put into one chunk before it is hashed; each slice has a fixed cost, so 5,000 chunks of 2 rows took 1.9 s and now take 0.02 s (F-076). The digest does not change.
- Records written before 0.7.0 have no
hash_method.lineage comparecalls them "not comparable" with new records rather than "changed", and calls two missing hashes "unknown" rather than "unchanged". - The
sample_fractionsetting is ignored and kept only so old configs load.
Addendum (0.7.0): run record v2, the receipt says why
A v1 record could show that two runs wrote different data, not why: the
transform, an input or the machine could each have moved. Version 2
(record_version: 2) adds what answers that:
| Field | What it is |
|---|---|
code_hash |
sha256: of every .py file in the task folder (paths and contents, line endings normalised, caches and hidden folders skipped) |
environment, environment_hash |
Python version and implementation, platform, machine, and the versions of the packages that can change a result (engine, pyspark, delta-spark, pandas, pyarrow, numpy, narwhals, scikit-learn, torch, mlflow) |
inputs[*].data_hash, row_count, schema_hash |
every input hashed exactly like the outputs (rows-v1) |
timings |
one entry per read, transform and write, with seconds; kept when the run fails |
inputs[*].hash_seconds, outputs[*].hash_seconds |
how long that data hash took; it runs after the writes, so it is in no timing (F-014) |
inputs[*].hash_basis, outputs[*].hash_basis |
materialised: the digest is of the rows that were written (a held Spark output, a pandas frame); recomputed: the frame was computed again for the hash (a Spark input, or an output that could not be held). ADR 009 |
inputs[*].hash_reused_from, outputs[*].hash_reused_from |
set when the same frame was already hashed for another step of the run, which it names (output:<name>); hash_seconds is then 0 |
expectations |
every CONFIG.expectations rule checked, passed or not; kept when the run fails |
model_runs |
(0.9) each model a ModelTransform trained or used: version, stage, and for training the gate result; kept when the run fails. ADR 012 |
ubunye lineage compare reports each of these as changed or unchanged, and
names the packages whose versions moved. ubunye lineage trace prints them.
Hashing inputs costs one more scan of each input. On Spark that scan reads the
source again, after the writes: it is not the rows the transform read, so a source
that changes between the read and the hash (another job appends, a file is replaced,
the task overwrites its own input) gives an input digest of the later state. Inputs
are not held (ADR 009); every Spark input step says hash_basis: recomputed.
It is on by default; a
recorder built with LineageRecorder(hash_inputs=False) skips it for inputs too
large to read twice, and those inputs then show - for their row count.
The record says whether an input's digest is of what was read (F-046). The engine takes each input's source version right after the read (only in a recorded run that hashes inputs), and the recorder checks it again right after that input's hash. Nothing is read from the data for it:
| Source | Version |
|---|---|
Delta (delta by path or table, s3 with file_format: delta) |
the version the read is pinned to: by the config (version_as_of, timestamp_as_of, or versionAsOf / timestampAsOf in options, any case), or else by the engine, which pins the read to the version the table is at when it is read |
a Delta catalog table (hive, unity) |
the table version and its time, from the Delta log (not pinned) |
files (s3, binary, a pandas read) |
the files the frame reads (Spark's file index, inputFiles()): count, bytes, latest modification time, whether every file has a content tag (etags), and a hash of the sorted (relative path, size, time, etag) list |
a SQL query, JDBC, a REST API, a catalog table that is not Delta, Spark Connect, a listing that failed, a version that took longer than UBUNYE_SOURCE_VERSION_TIMEOUT (30 s) |
none, with the reason |
| Field | What it is |
|---|---|
inputs[*].source_version |
the version at the read |
inputs[*].source_version_at_hash |
the version right after the hash (a recomputed input with a version only); for a pinned Delta read, the table's latest_version then, as information; for an unpinned Delta table, commits_since_read |
inputs[*].source_changed |
true: the digest is of a later state than the one read; false: see below; missing: not known |
inputs[*].source_note |
the same in one sentence |
source_changed: false means exactly what the note says:
- a pinned Delta read: the digest is of what was read, by construction;
- an unpinned Delta table: same version, or only commits that change no rows since the read (OPTIMIZE, VACUUM, table properties, constraints);
- files with content tags (S3A, ABFS on Hadoop 3.3 and later): same names, sizes, times and tags, so the digest is of what was read;
- files without them (a local disk, HDFS): same names, sizes and times only. A file rewritten with the same size and time cannot be ruled out, and the note says so.
A listing that fails (a throttle, a 503) is never read as missing files: the version is
none and the change unknown. Only a definite "not found" counts as missing.
A Delta read is pinned. A lazy Delta frame reads the latest version on every action,
so before this one input could feed two outputs from two versions (10 rows and 13, when
another job appended between them) and the input hash could read a third. A Delta read
that names no version now carries versionAsOf for the version the table is at when it
is read, so the transform, every output and the hash see one snapshot. This changes what
a Delta read reads, on purpose: a run that saw a table move while it ran now gives
outputs from one version, not a mix. A read the config pins is left as written. If the
version cannot be read, the read is left unpinned, as before.
hash_basis keeps its meaning (how the digest was computed); source_changed is
whether the source moved while it was. lineage compare calls such an input's hash
"unknown", and ubunye gate warns and counts it as a possible cause of a changed
output, never as proof the input was the same. The digest itself and the default
(hash every input) do not change. Measured on live Spark: a Delta table appended to
after the read is not read (the digest is of version 0, 10 rows; latest_version 1);
a parquet file rewritten after the read is flagged; a file added to the folder after
the read is not flagged, and rightly: Spark's file index keeps the files listed at the
read, so the hash does not read the new file. Cost (dev box, local disk): one file read
from a folder of 10,000: 0.005 s; 1,000 files in 1,000 folders: 1.6 s; 10,000 files in
one folder: 4.3 s (for scale: Spark took 54 s to build that frame); a Delta history
about 0.16 s. Up to 1,000 files, each file read is asked for its status; above that,
each folder is listed once.
Monitors receive the new evidence (inputs, expectations, timings) only if
their task_end accepts those arguments (or **kwargs), so monitors written
for 0.7 keep working unchanged. A v1 record loads as record_version: 1 with
the new fields empty.