Expectations
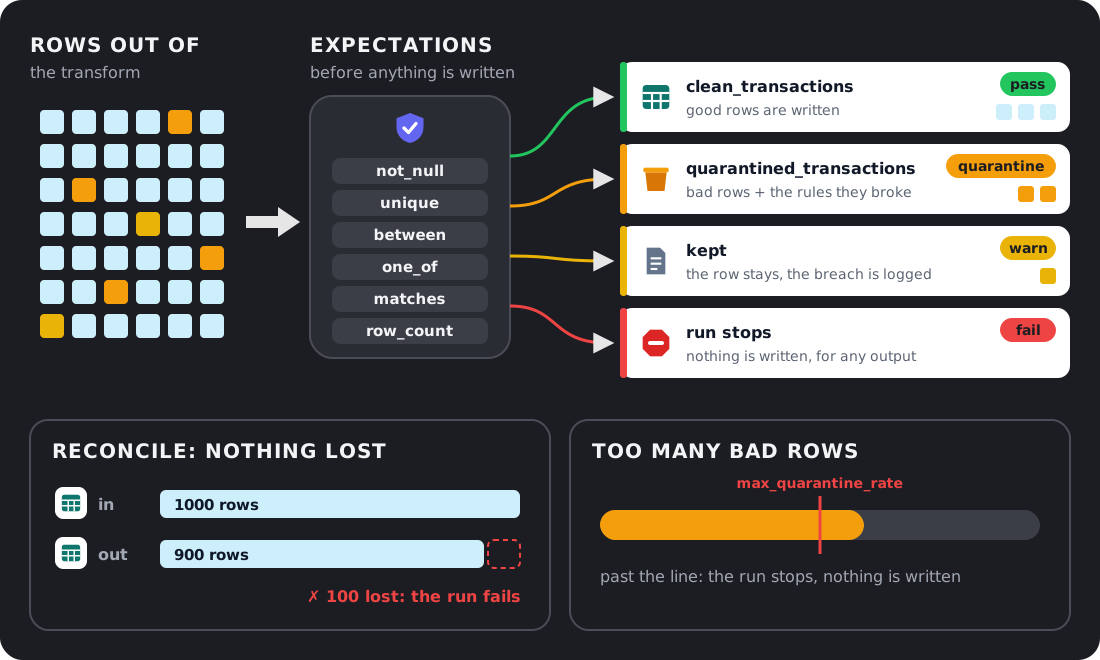
CONFIG.expectations states what an output must look like: rules such as "this
column is never empty". This page is for anyone who wants bad data to stop a run
instead of landing in a table. The engine checks every output after the transform
and before anything is written, on Spark and on pandas alike. It can also state
what an input must look like: see Input contracts.
CONFIG:
  inputs:
    transactions: {format: s3, path: "data/transactions.csv", file_format: csv}
  outputs:
    clean_transactions: {format: s3, path: "out/clean", file_format: parquet}
    quarantined_transactions: {format: s3, path: "out/quarantine", file_format: parquet}

  expectations:
    clean_transactions:                      # the output being checked
      quarantine: quarantined_transactions   # where bad rows go
      max_quarantine_rate: 0.05              # more than 5% bad: stop the run
      rules:
        - not_null: transactionID            # severity fail is the default
        - unique: transactionID
        - between: {column: quantity, min: 1}
          severity: quarantine
        - one_of: {column: paymentMethod, values: [visa, mastercard, amex]}
          severity: quarantine
        - matches: {column: cardNumber, pattern: '^\d{4}$'}
          severity: warn
        - row_count: {min: 1}
The rules
| Rule | Passes when | Per row? |
|---|---|---|
not_null: col |
the value is present | yes |
between: {column, min, max} |
min <= value <= max (either bound may be left out) | yes |
one_of: {column, values} |
the value is in the list | yes |
matches: {column, pattern} |
the value matches the regular expression | yes |
unique: col or [col, ...] |
no two rows share the value(s) | no |
row_count: {min, max} |
the number of rows is in range | no |
columns: {col: type, ...} |
each column exists with that type; see Input contracts | no |
A missing value passes every rule except not_null, as in SQL. When a value must
be present and valid, write both rules. In a float column NaN counts as missing, like
null, on every backend: pandas stores a missing float as NaN and cannot tell the two
apart, so this is the one rule both backends can keep. not_null breaks on NaN;
between and one_of let it pass.
Each rule is named after its column and kind (quantity_between), or give it a
name:. Names must be unique within an output.
What a broken rule does
severity |
Effect |
|---|---|
fail (default) |
The run stops. Nothing is written, for any output. |
quarantine |
The breaking rows move to the quarantine: output, with a _ubunye_failed_rules column naming every rule each row broke, and only those, in the order they are declared (quantity_between,paymentMethod_one_of), the same on every backend. The rest are written. Only per-row rules can quarantine. |
warn |
The rows stay; the breach is logged. |
The quarantine output is always written, empty when no row broke a rule, so a downstream job can rely on it. The transform must not return it: the engine fills it.
max_quarantine_rate turns "a few bad rows" into "the source has changed": if a
larger share of rows is quarantined, the run fails and nothing is written.
When it fails
ExpectationError: Expectations failed, so nothing was written:
  clean_transactions: transactionID_not_null (not_null) broken by 1 of 891 rows
  Hint: Fix the data or the source, or change the rule's severity to quarantine
  or warn if this is expected.
The hint names only what the broken rules can do:
| Broken rule | The hint suggests |
|---|---|
a rule on rows (not_null, between, one_of, matches) |
quarantine or warn |
a reconcile |
a share (max_lost: "1%") or warn |
unique, row_count, columns (these cannot quarantine) |
warn |
What you see:
ubunye runprints the message and exits with code 1, with no traceback: the data broke a rule, the engine did not crash.- An
ExpectationErrorabout the setup, such as narwhals not installed, still shows its traceback. - From Python, the error carries every rule's result, passed or not
(
err.results). A rule that breaks zero rows today and thousands tomorrow is the earliest warning that something upstream moved.
Reconcile: nothing lost on the way
A join can drop rows and the run still succeeds. reconcile compares an output
with an input the transform received, before anything is written:
  expectations:
    enriched:
      reconcile:
        - input: orders
          rows: {max_lost: 0}                    # every order reaches enriched
          sum: {column: amount, tolerance: 0.01} # and so does its amount
| Key | Meaning |
|---|---|
input |
an input in CONFIG.inputs |
rows: {max_lost, max_gained} |
how many rows may be lost, or gained (a join that fans out). A number of rows, or a share of the input: "1%". A bound left out is not checked. |
sum: {column, input_column, tolerance} |
the column's sum must match the input's. input_column is the input's name for it, if different. tolerance is a number, or a share of the input's sum ("0.1%"); default 0. |
severity |
fail (default) or warn |
Each check is reported like a rule, named rows_from_orders and
amount_sum_from_orders, with what was found:
ExpectationError: Expectations failed, so nothing was written:
  enriched: rows_from_orders (reconcile): 1000 rows read from orders, 900 reached
  enriched: 100 lost, 0 gained (at most 0 lost)
- The input is counted before the transform runs. A pandas transform can
change its input in place (
drop(..., inplace=True),orders["amount"] = 0); counting afterwards would hide the very loss a reconcile is for. - Quarantined rows count as carried over. They were set aside with a reason, not lost. The output is counted before any row moves to its quarantine output.
- Counting rows sees the net change only. A join that loses 5 rows and
duplicates 5 others shows 0 lost and 0 gained.
max_gainedbounds a fan out, and auniquerule on the key catches the duplicates. - A filter that drops rows on purpose needs a share (
max_lost: "30%"), or no row reconcile at all;max_lost: 0would stop every run. - Sums are exact for integers (no wrap past 2**63) and decimals (no rounding through a float); the message prints them in full. A sum leaves out missing values (null, and NaN in a float column) on both sides, as the rules do. Two equal totals match, infinities included. Float sums can differ in the last digits when rows move, so give a float sum a small tolerance.
- Two checks against one input need a
name(the results are then<name>_rowsand<name>_sum), for example a warning at 1% and a stop at 5%:
      reconcile:
        - {input: orders, name: early, rows: {max_lost: "1%"}, severity: warn}
        - {input: orders, name: stop, rows: {max_lost: "5%"}}
- Cost: one pass over each reconciled input, for its row count and sums, however
many outputs reconcile with it. On pandas that is in memory. On Spark it reads the
input again, because inputs are not held in memory. On the output side the rows are counted in
the same pass as the other rules, and sums in a pass of their own over the held
output. On Spark an integer sum is taken as
decimal(38,0); a decimal sum past 38 digits fails (ANSI) or comes back null. - In a notebook the check compares with what the transform got: the frames
read()returned, or the ones you passed totransform(). They are counted whentransform()starts.
Input contracts
A source can change under you. When price arrived as text, pandas computed
qty * price as "11.011.0" and the run succeeded. Name the input under
expectations, and its rules run right after it is read, before the
transform:
  expectations:
    orders:                                  # an input, not an output
      rules:
        - columns: {order_id: int64, qty: int64, price: float64}
          extra: allow                       # default; forbid refuses other columns
        - not_null: order_id
ExpectationError: An input broke its expectations, so the transform did not run
and nothing was written:
  orders: columns (columns): price: expected float64, found string
The columns rule:
- Type names are the run record's, the same on Spark and pandas:
int8,int16,int32,int64,float32,float64,bool,string,binary,date,timestamp,timestamp_ntz,decimal(p,s),list<...>,map<...,...>,struct<name:type,...>. Spark'sdoubleisfloat64,bigintisint64;ubunye validatesays so if you write the other name. Nested names are checked part by part (list<banana>is refused). A frame can also reportuint8touint64,null(a column of nulls only),mixed(a pandas column of mixed Python values),time64[us]and the like; those can be declared too. - A timestamp is named by what it is: with a zone
timestamp, without onetimestamp_ntz, on pandas as on Spark 3.4 and later, at every depth. So a source that switches between naive and UTC is caught. This differs from the run record, which writes every pandas timestamp as an instant and names ittimestamp; the record (and its schema hash) is unchanged. - CSV: with
inferSchema, a whole number column isint32when every value fits, elseint64, on both engines. A column that may grow, declare as[int32, int64]. WithoutinferSchemaevery column isstring. - Types match exactly.
int32is notint64: a narrower or wider type is a changed source, and it changes what the task writes. To accept more than one, list them:qty: [int32, int64]. - Nulls are not part of the type. A column of
int64with gaps isint64. - A column that is missing, has another type or (with
extra: forbid) is not declared is named, each on its own. The result'sdetailholds them all. - It reads the schema only; no row is read. If a
columnsrule with severityfailbreaks, the other rules on that frame are not run.
Any rule can go on an input: not_null, between, unique, and so on. They cost
one pass over the input; on Spark that reads the source again, since inputs are
not held in memory. The results are in the run record with side: input.
An input cannot quarantine rows (yet), and cannot have a reconcile (that goes on
the output). A name that is both an input and an output cannot have expectations:
rename one. columns works on an output too, to pin what the task writes.
Checked when the config loads
ubunye validate refuses:
- an expectation that names no input or output, or a name that is both;
- an input with a quarantine or a reconcile;
- a
columnstype that is not one of the names above; - a quarantine output that does not exist, or is the output itself;
- two outputs sharing one quarantine output;
- a rule with no kind, or two kinds;
- a
quarantinerule with noquarantine:output; - a
matchespattern that is not a valid regular expression; - a
reconcilethat names no real input, checks nothing, or has a bound that is not a number or a percentage.
Why inputs are read again on Spark instead of held: ADR 009.